Introduction
Spaghetti code is hard to work with because its logic is tangled. A function in Python can handle several related steps and still be perfectly readable. Problems start when different responsibilities become tightly connected, dependencies are unclear, and changing one piece of logic requires tracing through unrelated parts of the code.
Breaking code into…
Most production AI agents still send every LLM call to the same expensive frontier model. Classification steps, simple tool calls, progress checks, and hard reasoning all hit the same endpoint. The result is unnecessary cost and latency. NVIDIA NeMo Switchyard solves this.
It is an open-source routing layer (proxy + library) that sits between your…
The Problem With Static User Profiles
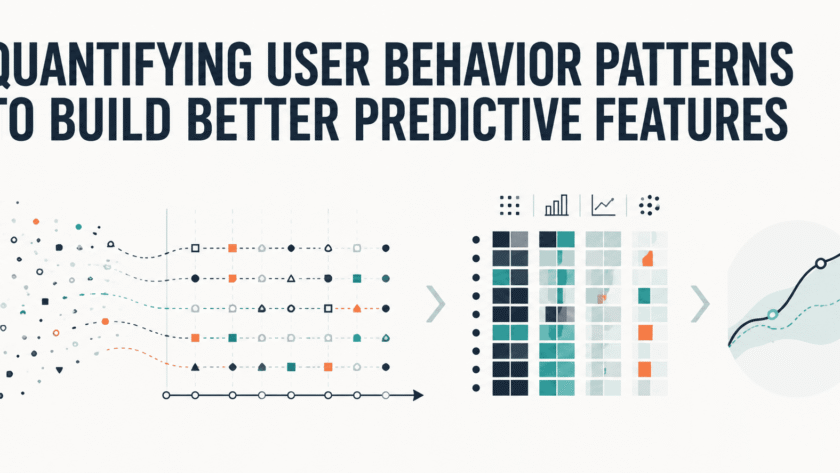
Traditional models treat users as fixed entities, reducing complex decision-makers to demographics and aggregate metrics. Simply knowing that a 35-year-old male in Seattle clicked 12 times last month tells you almost nothing about his intent. These macroscopic features fail to capture the moment-to-moment shifts that signal genuine interest or…
Introduction
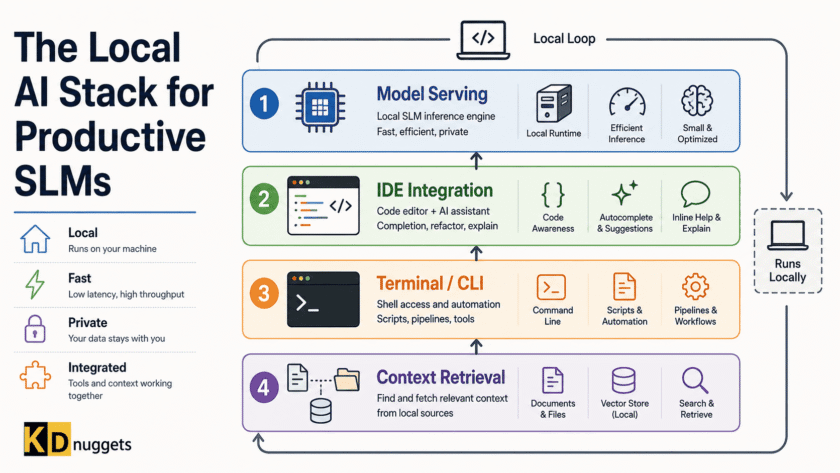
Running a small language model locally is straightforward. Running one productively — inside a real development workflow, with proper context, tool access, and iteration speed — is a different problem entirely.
The gap between "I got a model responding in my terminal" and "I have a local AI setup that actually improves how I…
Muse Glimmer is gaining attention in the local AI community and is being compared with Qwen's 27B-class models. In many cases, it is performing better, especially for local coding and agentic workflows.
Meta looks strong in the open-model space, and with a few more iterations, models like this could start competing closely with proprietary systems.…
Running a capable 27B model as a local AI coding agent used to mean setting up inference servers, configuring endpoints, and connecting everything manually. With Qwen3.8-27B, Ollama, and OpenCode, the process is now remarkably straightforward.
Qwen3.8-27B is one of the local models I have been most excited to try. It is strong at coding, reasoning,…
"Streaming" gets used in two different ways when people talk about AI agents, and most tutorials only build one of them. Sometimes it means the agent consumes a live stream of events instead of waiting for someone to type a message. Sometimes it means the agent's own output streams out token by token instead…
# Small But Powerful
Running a 70B model in production can be expensive, slow, and, for many tasks, unnecessary. If you're building a focused pipeline like a document classifier or a multilingual support responder, a well-trained 3B model will match or beat the 70B on your specific task at a fraction of the…
★ Editor's Pick — Most Read Article This Week
7 Steps to Building and Deploying Your First Autonomous Agent Shittu Olumide · Artificial Intelligence · July 27, 2026 The process outlines how to transition autonomous AI agent prototypes into production-ready systems by focusing on robust orchestration and deployment practices. Successful agent development requires…
# Introduction
The narrative around generative AI is shifting in 2026. While massive frontier models keep grabbing headlines, the reality of enterprise AI deployment looks very different. Cost constraints, latency limits, and strict data privacy requirements have pushed engineering teams away from trillion-parameter behemoths and toward small language models (SLMs). Ranging from 1…